• Home
  • Papers
  • Courses
  • Readings
  • Notes
  • Classics
  • Calendar
ESC

Searching...

No results found

↑↓ Navigate ↵ Select
Powered by Hugo Blox
  • Recorded Readings
    • The American Way of Killing
      • Overview
    • The Map of My Life
    • The Nvidia Way
    • My Journeys in Economic Theory
    • When Genius Failed
    • Breakneck
    • 我只会算术,惰者集
    • 数学与创造,可变思考
    • 世界是概率的
    • 张忠谋自传
    • 春夜十话
    • Breaking Through
    • The Thinking Machine
    • The Dean of Shandong
    • The Random Walk Guide to Investing
    • In A Flight of Starlings
    • Eye of the Hurricane
  • Inside An Academic Scandal
  • Courses
    • Introduction to Machine Learning
    • Theory and Applications of Generative Models
    • Optimization for Data Science
  • Publications
    • Nonlinear Axiomatic Attribution for Cooperative Games
    • Provably Adaptive Linear Approximation for the Shapley Value and Beyond
    • Efficient Bilevel Optimization with KFAC-Based Hypergradients
    • SFBD Flow: A Continuous-Optimization Framework for Training Diffusion Models with Noisy Samples
    • SFBD-OMNI: Bridge models for lossy measurement restoration with limited clean samples
    • TreeGrad-Ranker: Feature Ranking via O(L)-Time Gradients for Decision Trees
    • Demystifying Foreground-Background Memorization in Diffusion Models
    • Adaptive Context Length Optimization with Low-Frequency Truncation for Multi-Agent Reinforcement Learning
    • BridgePure: Limited Protection Leakage Can Break Black-Box Data Protection
    • DiffBreak: Is Diffusion-Based Purification Robust?
    • Uncoupled and Convergent Learning in Monotone Games under Bandit Feedback
    • MUC: Machine Unlearning for Contrastive Learning with Black-box Evaluation
    • A Comprehensive Framework for Analyzing the Convergence of Adam: Bridging the Gap with SGD
    • Stochastic Forward-Backward Deconvolution: Training Diffusion Models with Finite Noisy Datasets
    • Diffusion Models under Group Transformations
    • Leveraging Variable Sparsity to Refine Pareto Stationarity in Multi-Objective Optimization
    • Last-iterate Convergence in Regularized Graphon Mean Field Game
    • Disguised Copyright Infringement of Latent Diffusion Models
    • Noise-Aware Aggregation for Heterogeneous Differentially Private Federated Learning
    • Indiscriminate Data Poisoning Attacks on Pre-trained Feature Extractors
    • Convergence to Nash Equilibrium and No-regret Guarantee in (Markov) Potential Games
    • Faster Approximation of Probabilistic and Distributional Values via Least Squares
    • One Sample Fits All: Approximating All Probabilistic Values Simultaneously and Efficiently
    • Robust Data Valuation with Weighted Banzhaf Values
    • Understanding Neural Network Binarization with Forward and Backward Proximal Quantizers
    • Batchnorm Allows Unsupervised Radial Attacks
    • $f$-MICL: Understanding and Generalizing InfoNCE-based Contrastive Learning
    • MT-MAG: Accurate and interpretable machine learning for complete or partial taxonomic assignments of metagenome-assembled genomes
    • CM-GAN: Stabilizing GAN Training with Consistency Models
    • Exploring the Limits of Model-Targeted Indiscriminate Data Poisoning Attacks
    • Functional Rényi Differential Privacy for Generative Modeling
    • Operator Selection and Ordering in a Pipeline Approach to Efficiency Optimizations for Transformers
    • Distilling the Knowledge in Diffusion Models
    • Multi-Objective Reinforcement Learning: Convexity, Stationarity and Pareto Optimality
    • Proportional Fairness in Federated Learning
    • Indiscriminate Data Poisoning Attacks on Neural Networks
    • A Unifying Framework for Federated Learning
    • Network Comparison with Interpretable Contrastive Network Representation Learning
    • FedMGDA+: Federated Learning meets Multi-objective Optimization
    • Conditional Generative Quantile Networks via Optimal Transport
    • Revisiting flow generative models for Out-of-distribution detection
    • Optimality and Stability in Non-Convex Smooth Games
    • Are My Deep Learning Systems Fair? An Empirical Study of Fixed-Seed Training
    • Demystifying and Generalizing BinaryConnect
    • Quantifying and Improving Transferability in Domain Generalization
    • S$^3$: Sign-Sparse-Shift Reparametrization for Effective Training of Low-bit Shift Networks
    • The Art of Abstention: Selective Prediction and Error Regularization for Natural Language Processing
    • Newton-type Methods for Minimax Optimization
    • Posterior Differential Regularization with $f$-divergence for Improving Model Robustness
    • BERxiT: Better-fine-tuned and Wider-applicable Early Exit for *BERT
    • Problems and Opportunities in Training Deep-Learning Software Systems: An Analysis of Variance
    • Unsupervised Multilingual Alignment using Wasserstein Barycenters
    • Early Exiting BERT for Efficient Document Ranking
    • DeepAntigen: a novel method for neoantigen prioritization via 3D genome and deep sparse learning
    • A novel neoantigen discovery approach based on chromatin high order conformation
    • Density Deconvolution with Normalizing Flows
    • DeeBERT: Dynamic Early Exiting for Accelerating BERT Inference
    • Showing Your Work Doesn't Always Work
    • Convex Representation Learning for Generalized Invariance in Semi-Inner-Product Space
    • On Minimax Optimality of GANs for Robust Mean Estimation
    • Tails of Lipschitz Triangular Flows
    • Stronger and Faster Wasserstein Adversarial Attacks
    • Convergence of Gradient Methods on Bilinear Zero-Sum Games
    • Understanding Adversarial Robustness: The Trade-off between Minimum and Average Margin
    • Least-Squares Estimation of Weakly Convex Functions
    • A Penalized Regression Model for the Joint Estimation of eQTL Associations and Gene Network Structure
    • Multivariate Triangular Quantile Maps for Novelty Detection
    • Sum-of-squares Polynomial Flow
    • What Part of the Neural Network Does This? Understanding LSTMs by Measuring and Dissecting Neurons
    • Orpheus: Efficient Distributed Machine Learning via System and Algorithm Co-design
    • Inductive Two-Layer Modeling with Parametric Bregman Transfer
    • Deep Homogeneous Mixture Models: Representation, Separation and Approximation
    • Distributed Proximal Gradient Algorithm for Partially Asynchronous Computer Clusters
    • Bregman Divergence for Stochastic Variance Reduction Methods: Adversarial Prediction and Saddle-Point Problems
    • Efficient Multiple Instance Metric Learning using Weakly Supervised Data
    • Convex-constrained Sparse Additive Modeling and Its Extensions
    • Robust Top-$k$ Multiclass SVM for Visual Category Recognition
    • Learning Latent Space Models with Angular Constraints
    • Inference of Multiple-wave Population Admixture by Modeling Decay of Linkage Disequilibrium With Polynomial Functions
    • Dropout with Expectation-Linear Regularization
    • Generalized Conditional Gradient for Sparse Estimation
    • Closed-Form Training of Mahalanobis Distance for Supervised Clustering
    • They Are Not Equally Reliable: Semantic Event Search using Differentiated Concept Classifiers
    • Convex Two-Layer Modeling with Latent Structure
    • Semantic Pooling for Complex Event Analysis in Untrimmed Videos
    • Additive Approximations in High Dimensional Nonparametric Regression via the SALSA
    • On Convergence of Model Parallel Proximal Gradient Algorithm for Stale Synchronous Parallel System
    • Scalable and Sound Low-Rank Tensor Learning
    • Lighter-Communication Distributed Machine Learning via Sufficient Factor Broadcasting
    • Online Learning and Optimization
    • Exact Algorithms for Isotonic Regression and Related
    • Searching Persuasively: Joint Event Detection and Evidence Recounting with Limited Supervision
    • Petuum: A New Platform for Distributed Machine Learning on Big Data
    • Linear Time Samplers for Supervised Topic Models using Compositional Proposals
    • Semantic Concept Discovery for Large-Scale Zero-Shot Event Detection
    • Complex Event Detection using Semantic Saliency and Nearly-Isotonic SVM
    • Minimizing Nonconvex Non-Separable Functions
    • Efficient Structured Matrix Rank Minimization
    • Better Approximation and Faster Algorithm Using the Proximal Average
    • Polar Operators for Structured Sparse Estimation
    • Characterizing the Representer Theorem
    • On Decomposing the Proximal Map
    • A Polynomial-time Form of Robust Regression
    • Accelerated Training for Matrix-Norm Regularization: A Boosting Approach
    • Convex Multi-view Subspace Learning
    • Analysis of Kernel Mean Matching under Covariate Shift
    • Regularizers versus Losses for Nonlinear Dimensionality Reduction
    • Convex Sparse Coding, Subspace Learning, and Semi-Supervised Extensions
    • Distance Metric Learning by Minimal Distance Maximization
    • Rank/Norm Regularization with Closed-Form Solutions: Application to Subspace Clustering
    • Relaxed Clipping: A Global Training Method for Robust Regression and Classification
    • A Conditional Value-at-Risk Approach for Uncertain Markov Decision Processes
    • A General Projection Property for Distribution Families
    • Online TD(1) Meets Offline Monte Carlo
  • Numbers Rule
  • Making Democracy Count
  • The (Mis)behavior of Markets
  • Prisoner's Dilemma
  • Finding Equilibrium
  • To Pixar and Beyond
  • The Ethical Algorithm
  • The Gravity of Math
  • The Wisdom of Crowds
  • Source Code
  • The Last Man Who Knew Everything
  • The Laws of Thought
  • The Money Trap
  • Revenge of the Tipping Point
  • Some Classic Papers
  • Some Notes

On this page

  • Overview
Recorded Readings
The American Way of Killing

The American Way of Killing

Oct 4, 2026·
Yaoliang Yu
Yaoliang Yu
· 1 min read
Table of Contents
  • Overview

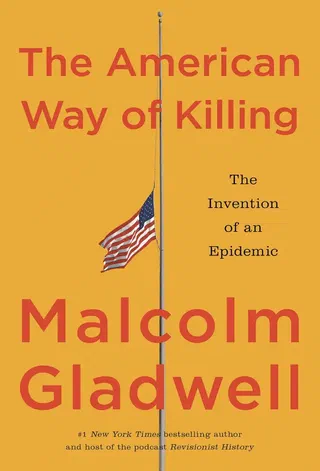
By Malcolm Gladwell (Little Brown, 2026).

Overview

Another eye-opener from Gladwell. Oh boy, the absurdity!

Last updated on Oct 4, 2026
Book History Social Science Political Science
Yaoliang Yu
Authors
Yaoliang Yu

The Map of My Life Aug 22, 2026 →

Related

  • Inside An Academic Scandal
  • Finding Equilibrium
  • The Map of My Life
  • The Nvidia Way
  • My Journeys in Economic Theory

© 2024-2026 Yaoliang Yu. This work is licensed under CC BY NC ND 4.0

Made with Hugo Blox — Open Source. Create yours →